Gluesync Automator 

Gluesync Automator is a standalone executable that provides a user-friendly web interface to run the Gluesync Bootstrapper’s create_all_entities.py script without requiring Python dependencies or command-line knowledge. It also exposes backup, restore, duplication, and bulk discovery workflows that sit on top of the same Bootstrapper primitives, making day-two operations approachable for non-developers.
|
Automator is the authoritative tool for platform backups and restores. When documentation mentions backing up or moving Gluesync environments, it is explicitly referring to Automator’s export/import flows described below. |
 This project is Open Source
Overview
The Automator packages the Bootstrapper functionality into a single executable file that launches a local web server bound to your machine on port 8080. It provides a graphical interface for:
-
Authenticating with Gluesync Core Hub
-
Uploading YAML configuration files
-
Configuring entity creation options
-
Monitoring live logs during execution
-
Downloading logs for troubleshooting
This makes the Bootstrapper accessible to users who prefer graphical tools over command-line interfaces, while maintaining all the underlying automation capabilities.
Key features
-
Web-based interface
-
Accessible via any modern browser at
localhost:8080 -
Responsive design works on desktop and mobile devices
-
Gluesync-branded interface matching documentation styling
-
-
Resilient authentication
-
Secure login to Core Hub with TLS options
-
Certificate verification controls and skip-verify switch
-
Automatic retry on transient network failures, with clear UI log messages
-
-
Configuration management
-
Drag-and-drop YAML file uploads plus schema overrides
-
Validation of configuration files (single pipeline or bulk archives)
-
Support for all Bootstrapper YAML formats, including unlocked schema and advanced filters
-
-
Entity creation options
-
Toggle automatic table creation and scheduling
-
Skip errors option for batch processing
-
Configurable chunk sizes for large deployments
-
Auto-detect pipeline schemas from YAML or manually override per run
-
-
Real-time monitoring & logging
-
Live streaming of backend execution logs, even for failures (returned as structured log arrays)
-
Color-coded status indicators (idle, running, completed, failed)
-
Import/export actions append detailed audit lines (agent matching, conductor deployment, polling status)
-
-
Agent lifecycle automation
-
Detects missing SOURCE/TARGET agents during imports
-
Optional “Automatically deploy missing agents via Conductor” checkbox (enabled by default)
-
Polls Core Hub until deployed agents become available before resuming the pipeline restore
-
-
Backup and restore tooling
-
Export single pipelines (metadata or full backup)
-
Export all pipelines with consolidated
agents-config.yamland UDF sources -
Validate and import ZIP archives with clear remediation hints when secrets are still masked
-
-
Bulk discovery
-
Discover schemas and tables from live Core Hub agents
-
Pick-and-choose tables, then create entities without crafting YAML
-
-
Cross-platform support
-
Native executables for Windows, macOS (notarized), and Linux
-
Self-contained with all dependencies bundled
-
Installation
Download
Download the latest Automator executable from the official distribution site:
You can also download the default Bootstrapper schema template used by Automator:
Executables are available for:
-
Windows (.exe)
-
macOS (.app inside a
.zip) -
Linux (.bin)
macOS notarization
The macOS build is code-signed with Developer ID Application: MOLO17 SRL (935BPM8A8T) and notarized via Apple’s notary service. Install it by:
-
Downloading
Gluesync-Automator-macOS.zip. -
Double-clicking the ZIP to extract
Gluesync Automator.app. -
Dragging the app into
/Applications. -
Run the app from
/Applications/Gluesync Automator.app.
No chmod, right-click, or security override is required. If the ZIP is copied via insecure channels and the quarantine bit gets added again, run xattr -cr "/Applications/Gluesync Automator.app" once to clear it.
Usage
Launching the Automator
-
Download the executable for your platform
-
Run the file (double-click on Windows/macOS, or execute in terminal on Linux)
-
The application will start a web server and open your default browser to
localhost:8080on your machine
Using the web interface
Authentication
-
Enter your Core Hub URL (e.g.,
localhost:1717reached over HTTPS) -
Provide your username and password
-
Optionally configure TLS settings:
-
Enable TLS for secure connections
-
Skip certificate verification if using self-signed certificates
-
-
Click "Login" to authenticate
After a successful login, the Core Hub URL, Username and Password fields become read-only so that the active session cannot be accidentally changed. To modify these values, first click Sign out and then log in again with the new settings.
If the network flakes during login, Automator automatically retries (up to two attempts) and surfaces the retry status in the activity log, so users don’t have to manually re-type credentials for transient failures.
Configuration upload
-
Click "Choose File" to select your YAML configuration file
-
The interface will validate the file format
-
Configure additional options:
-
Enable/disable automatic table creation
-
Enable/disable scheduling for created entities
-
Set chunk size for batch processing
-
Choose to skip errors during execution
-
Pipeline and schema selection
The Import card also lets you control which pipeline and schemas are used when running create_all_entities.py:
-
Pipeline selector
-
The Pipeline drop-down lists all available pipelines discovered from Core Hub.
-
You must select the target pipeline before starting entity creation.
-
-
Automatic schema detection from YAML
-
By default, Automator derives source and target schemas from the uploaded YAML file (for example, from the
schemassection or top-level schema keys). -
All discovered schema pairs are processed sequentially, calling
create_all_entities.pyonce per pair.
-
-
Customize source/target schemas (override YAML)
-
When the Customize source/target schemas (override YAML) checkbox is unchecked (default):
-
The Source schema and Target schema fields are hidden.
-
Automator uses only the schemas declared in the YAML file.
-
-
When the checkbox is checked:
-
The Source schema and Target schema fields become visible and editable.
-
The values entered here override the schema information in the YAML for the current run.
-
This mode is intended for advanced scenarios where you need to force a specific schema mapping.
-
-
Running entity creation
-
Click "Start" to begin the entity creation process
-
Monitor progress through the live log output
-
The status indicator will show "Running" during execution
-
Upon completion, the status will change to "Completed" or "Failed"
Log management
-
View real-time logs in the integrated terminal window
-
Logs are automatically scrolled to show the latest output
-
Download full logs for troubleshooting or audit purposes
Pipeline export and backups
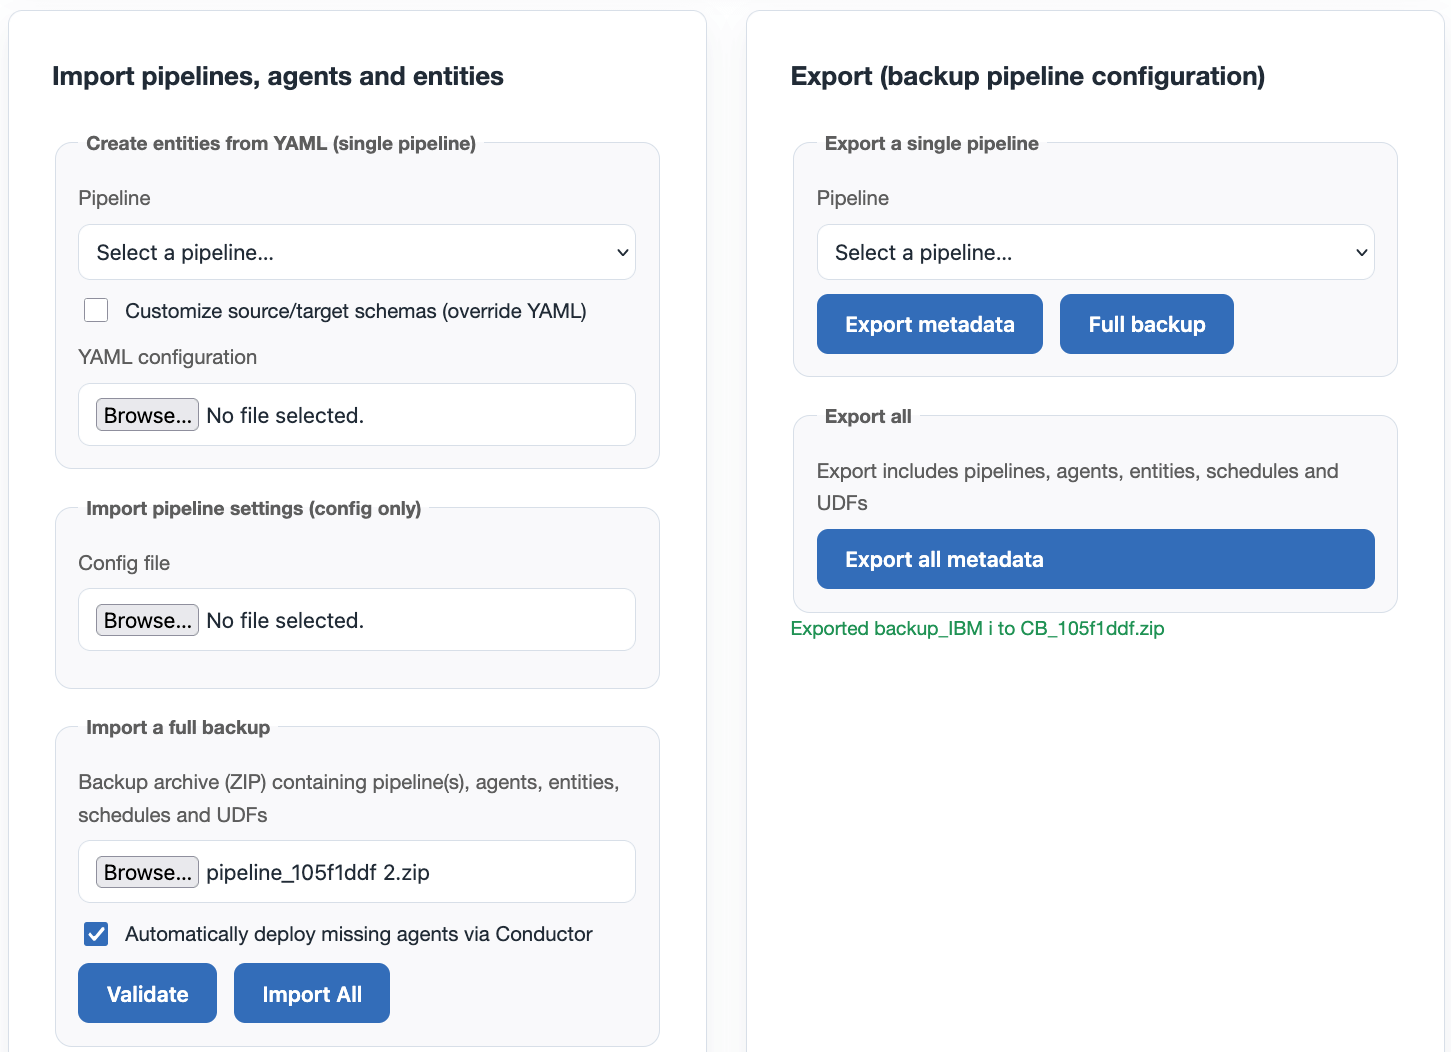
Automator also provides a dedicated Export card to back up existing pipeline configurations:
-
Pipeline selector: choose a pipeline to export (same list used by the Import and Bulk operations cards).
-
Export metadata: exports the selected pipeline configuration to a single table-list-style YAML file compatible with the Bootstrapper.
-
Full backup: exports the selected pipeline to a ZIP archive containing:
-
A table-list-style YAML file named
backup_<pipelineName>_<pipelineId>.yaml. -
A pipeline-scoped
agents-config.yamlwith agent definitions and pipeline metadata. -
The UDF source files referenced by that pipeline, grouped by owning agent in folders such as
udf-<agentId>/<UDF_NAME>.java(or other supported extensions).
-
-
Export all metadata: exports all pipelines in the Core Hub and returns them as a single ZIP archive.
These exports can be used as backups or as starting points for new Bootstrapper YAML configurations.
When you use Export all metadata, the downloaded ZIP archive contains:
-
One table-list-style YAML file per pipeline (named
backup_<name>_<pipelineId>.yaml). -
A consolidated
agents-config.yamlfile with:-
agents: a list of agent definitions matching the Bootstrapper config schema (agentType, agentTag, hostCredentials, customHostCredentials, specificConfiguration). -
pipelines: metadata that records the original pipeline IDs and names, and optionally anagentslist that specifies which agents (by agentType/agentTag) belong to each pipeline.
-
-
The UDF source files referenced by any exported pipeline, grouped by owning agent in folders such as
udf-<agentId>/<UDF_NAME>.java.
For security reasons, passwords inside hostCredentials are masked when exporting:
password: ******* # original password omittedBefore importing this configuration, you must edit the exported config to replace the * placeholders with real passwords. If masked passwords are still present when you attempt an import, the Automator will reject the request and display an error explaining that the passwords must be filled in first.
The Export card also provides import helpers:
-
Import config: accepts a single config file (JSON or YAML) shaped like the Bootstrapper’s
config.json/config.yamlexample. It creates a new pipeline in the target Core Hub and binds agents according to the file, but does not create entities or start syncs. -
Validate: accepts the same ZIP file as Import All or a single-pipeline Full backup and performs a dry-run validation. It checks that the archive structure is correct,
agents-config.yamlis well formed, passwords have been replaced, and each pipeline YAML contains at least one schema pair. The detailed validation report is printed in the Automator log panel, while the UI indicates whether the validation passed or failed. -
Import All: accepts the ZIP file produced by Export all metadata (or any ZIP following the same layout, including a single-pipeline Full backup) and recreates all pipelines contained in the archive. For each pipeline, it:
-
Creates a new pipeline (adding a
(restored)suffix to the name when needed to avoid name clashes). -
Binds the appropriate agents using the information from
agents-config.yaml. -
Applies each table-list YAML to create entities, without starting any syncs.
-
Automatically compiles and registers any UDFs referenced in the YAML using the exported source files from the backup, by invoking the same helper used by the Bootstrapper (
create_user_defined_functions.py). -
Detects whether each required agent is already available, unassigned, or missing entirely.
-
When the “Automatically deploy missing agents via Conductor” checkbox is enabled (default), Automator calls the Conductor APIs with the minimal env set required by
agents.json, waits for the deployments to register inside Core Hub, and only then resumes the import. -
If auto-deploy is disabled, the UI returns a structured log array spelling out which agents are missing so operators can provision them manually.
-
During import, the live log stream now contains detailed audit entries (prefixed with emoji markers) that surface unassigned agents, conductor deployment attempts, polling progress (⏳ Waiting for agents…, ✓ All deployed agents are now available after XXs) and any validation errors. Those logs are preserved even when the HTTP response indicates failure, so operators see exactly what happened without rummaging through local files.
For a step-by-step guide to backing up and restoring pipelines using Automator, see Backup and restore.
Bulk operations
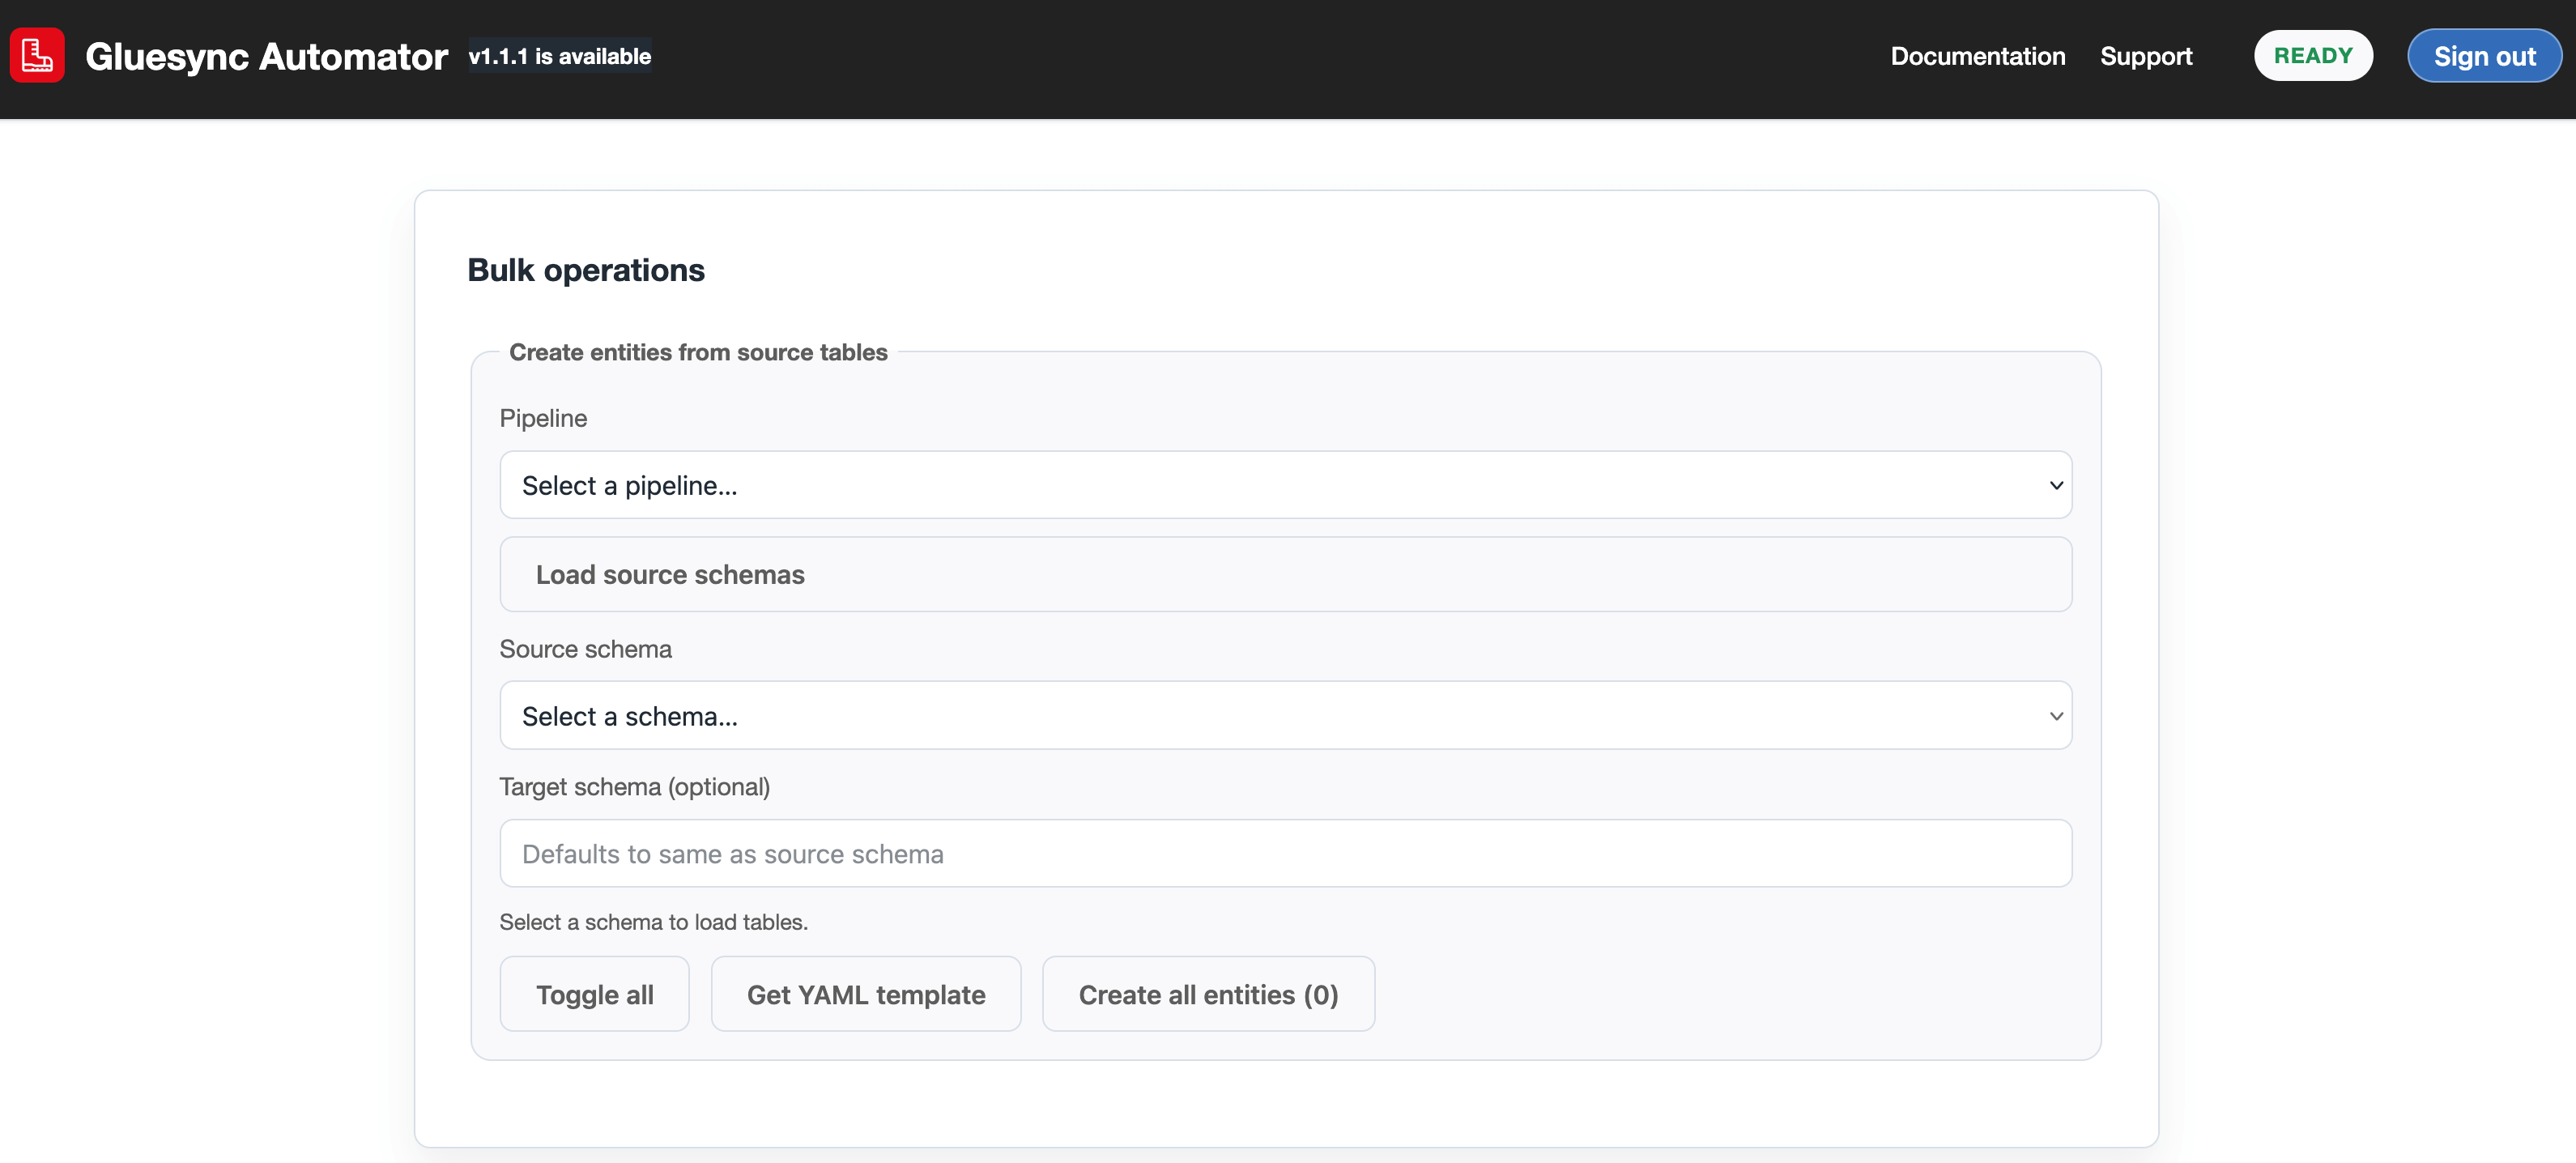
The Bulk operations card works as follows:
-
Pipeline
-
Drop-down listing all pipelines discovered from Core Hub (same list used by the Import and Export cards).
-
Selects the pipeline whose SOURCE agent will be used for discovery.
-
-
Source schema
-
After choosing a pipeline, Automator calls the Core Hub discovery API to list available schemas for the SOURCE agent.
-
The Source schema drop-down is populated from
/pipelines/<pipelineId>/agents/<sourceAgentId>/discovery/schemas.
-
-
Tables list
-
Once a schema is selected, Automator lists all tables discovered for that schema using
/pipelines/<pipelineId>/agents/<sourceAgentId>/discovery/tables?schema=<schema>. -
Each table appears with a checkbox; all tables are selected by default.
-
A short summary shows how many tables are available and how many are currently selected.
-
A Toggle all button lets you quickly select or deselect all tables.
-
-
Create all entities (N): build entities right away, automatically reusing discovery metadata from the selected SOURCE agent. To re-create only a handful of tables, deselect the others before running.
Bulk operations are optimized for the common case where you want to import "all tables from a given schema" (or a large subset) without maintaining a full table-list YAML. For advanced scenarios that require custom filters, UDFs, or group/schedule configuration, continue to use the YAML-based import flow described above.
Pipeline duplication
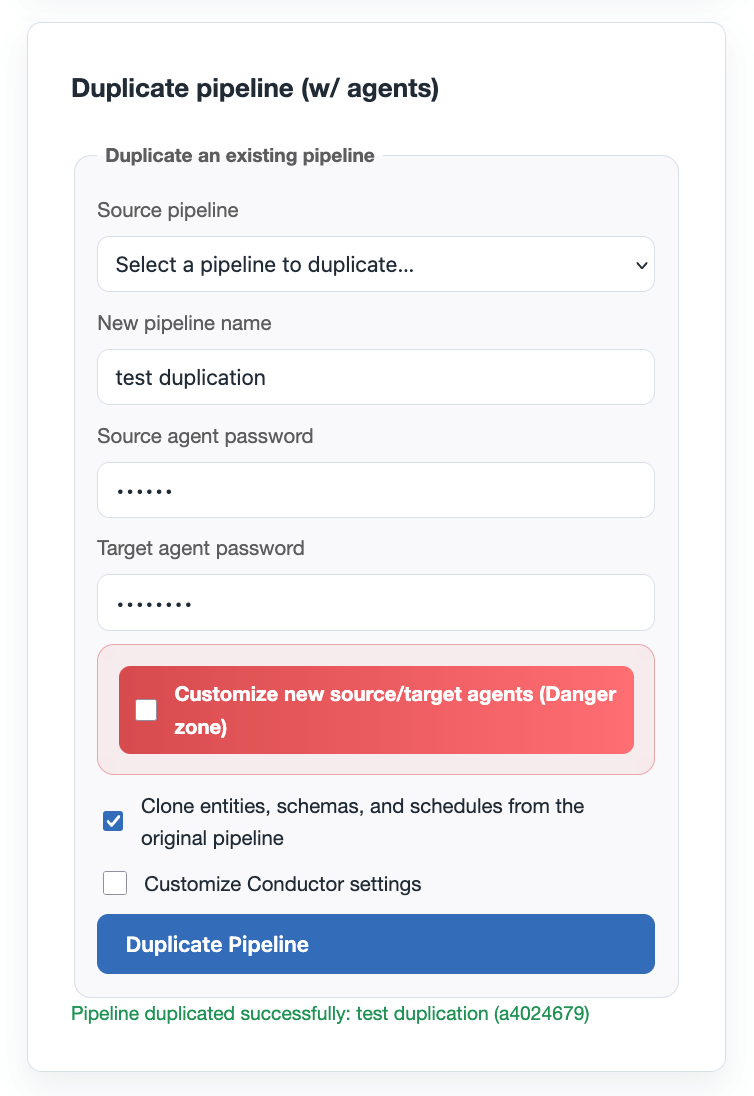
The Duplicate card lets you clone an existing pipeline into a brand-new one without exporting/importing archives.
Workflow:
-
Select the pipeline you want to clone. Automator immediately fetches the current SOURCE/TARGET agent tags so you can reuse them or override them.
-
Provide the new pipeline name and the Core Hub credentials for the SOURCE/TARGET agents that should back the clone.
-
Optional toggles:
-
Customize agents: Provide alternate agent tags if you want the duplicate to point to different pre-provisioned agents.
-
Clone entities: On by default. When enabled, Automator copies all existing entities from the original pipeline into the clone. When disabled, only the pipeline shell and agent bindings are created.
-
Customize Conductor URL: Supply a different Conductor base URL if the clone will auto-deploy missing agents in another environment.
-
-
Click Duplicate pipeline. The UI streams progress logs (agent binding, entity copying, config publishing) and lets you cancel an in-flight duplication via the same button.
Important behaviors:
-
Automator requires SOURCE/TARGET agent passwords before it can rebind or duplicate. The form validates that both are provided.
-
If the destination Core Hub is missing corresponding agents, you can leave Automatically deploy missing agents via Conductor enabled so the duplication flow provisions them just like the Import All wizard.
-
When cloning entities, Automator sets the
configurationCompletedflag toTruefor the newly created pipeline as soon as all entities finish transferring, ensuring the clone is ready to run without lingering in draft state.
Duplication is ideal for A/B pipelines, staging copies of production flows, or “same schema, different agents” scenarios where exporting/importing archives would be overkill.
Configuration options
TLS configuration
-
Enable TLS: Forces HTTPS connections to the Core Hub
-
Skip Certificate Verification: Bypasses SSL certificate validation (useful for development with self-signed certificates)
Entity creation settings
-
Create missing tables: Controls whether the Bootstrapper should generate CREATE TABLE statements for target databases
-
Enable scheduling: Automatically enables scheduled execution for created entities
-
Skip errors: Continues processing even if individual entities fail to create
-
Chunk size: Number of entities to process simultaneously (affects memory usage and performance)
-
Source/Target type: Drop-down selectors that map to the Bootstrapper’s agent types:
-
RDBMS (SQL) → sends
SQLto the backend and is used for relational/RDBMS sources or targets. -
Anything else → sends
NoSQLto the backend and is valid for document databases, event streaming platforms, object storage, or any non-RDBMS target.
-
These labels are purely UX improvements; the underlying values (SQL/NoSQL) remain backward compatible with existing scripts.
Troubleshooting
Common issues
| Issue | Possible cause | Resolution |
|---|---|---|
Application won’t start |
Port 8080 is already in use |
Close other applications using port 8080, or the Automator will prompt for an alternative port |
Authentication fails |
Incorrect Core Hub URL or credentials |
Verify the Core Hub is accessible and credentials are correct |
Configuration upload fails |
Invalid YAML format |
Validate your YAML file against the Bootstrapper schema |
Entity creation errors |
Network connectivity or Core Hub API issues |
Check Core Hub logs and network connectivity |
Slow performance |
Large chunk sizes or many entities |
Reduce chunk size or process entities in smaller batches |
Best practices
-
Store configuration files in version control alongside your infrastructure code
-
Test configurations in a development environment before production deployment
-
Keep executables updated to the latest version for security and feature improvements
-
Use consistent naming conventions for pipelines, entities, and schemas
-
Document your configuration choices for team knowledge sharing
-
Monitor Core Hub and Automator logs regularly for early issue detection
The Automator header displays the currently running version (for example, Automator v1.0.41). On startup it also performs a best-effort online check against the MOLO17 Backoffice API:
-
If a newer GA version is available, the header shows:
Automator vX.Y.Z – New version available: vA.B.C. -
A short inline changelog for the latest version is rendered below the header, together with a direct download link to https://molo17.com/gluesync-automator/.
-
If the remote services are not reachable, the UI silently falls back to showing the local version only and logs errors to the browser console for diagnostics.
Release notes
1.2.0
Released: March 4, 2026
-
Compatibility with Gluesync 2.2;
-
Embeds new Bootstrapper’s data type matrix from version 2.4.0;
-
Fixes and improvements;
1.1.11
Released: February 25, 2026
-
New schema input field for table creation when using bulk imports;
-
Improved error handling (erros are now pushed to the UI as well);
-
Fixed an issue with agent recognition (NoSQL vs RDBMS) during import operations;
-
Minor UI improvements;
1.1.10
Released: February 19, 2026
-
Fixed an issue with case sensitiveness applied when attempting to perform table’s creation;
-
Bootstrapper version bump to 2.3.12;
1.1.9
Released: February 2, 2026
-
Added support for SQL where clauses applied at source database level in Bootstrapper 2.3.10;
1.1.8
Released: January 21, 2026
-
Now supports CoreHub’s statistics retrieval;
-
Grouped tabs now allow for a better organization of commands;
-
Minor UI improvements;
1.1.6
Released: January 16, 2026
-
Improved pipeline duplication feature (now duplicates also UDFs, and allow for swapping schema names);
1.1.4
Released: January 14, 2026
-
Fixes on Chains backup & import;
-
Fixes on custom document ids import;
-
Fixes on entity name import;
-
Fixes on usage of source and target types;
-
New UI banner that displays the current corehub addres and total number of pipelines;
-
New duplicate pipeline feature extension:
-
Specify a different hostname for source/target agents;
-
Specify a different source/target schema name;
-
-
UI improvements;
-
Importing a pipeline now automatically generates new random ids to avoid conflicts with existing pipelines;
1.1.2
Released: January 13, 2026
-
Fixed an issue with columns mapping export;
-
Fixed an issue with entity name export;
1.1.1
Released: January 12, 2026
-
Added macOS notarized distribution (no more Gatekeeper “damaged” pop-ups).
-
Auto-deploy checkbox now defaults to on and shows granular logs for agent matching, conductor calls, and polling.
-
Import responses return structured log arrays even on failure, so the UI log panel always reflects backend output.
-
Fixed UDF compilation on read-only filesystems by relocating lock files under
~/Library/Logs/GluesyncAutomator/locks. -
Added automatic authentication retries for transient network failures.
1.1.0
Released: December 29, 2025
-
Added support for duplicating pipelines;
-
UI refinements;
-
Conductor’s APIs wire up;
1.0.7
Released: December 10, 2025
-
Ability to export UDFs;
-
Ability to perform bulk operations such as importing all tables from a given schema;
-
Support for Bootstrapper 2.3.5;
1.0.6
Released: December 8, 2025
-
Support for Bootstrapper 2.3.4;
-
Import & export pipeline configuration (incl. pipeline, agents, entities, and tables);
1.0.50
Released: December 6, 2025
-
Added support for Bootstrapper 2.3.2;
-
UI improvements;
-
Added support for updates checking;
1.0.41
Released: December 5, 2025
-
Added support for Bootstrapper 2.3.1;
-
Added support for pipeline export (also in bulk);
1.0.0
Released: November 2, 2025
-
Initial release of Gluesync Automator
-
Web-based UI for Bootstrapper functionality
-
Cross-platform executables (Windows, macOS, Linux)
-
Live log streaming and monitoring
-
Drag-and-drop configuration uploads
-
TLS and authentication options
-
Responsive design with Gluesync branding