No central store. No rewrites.
Connect every system. Move every change. In real time.
Move operational data between databases, APIs, lakes, and event streams as it changes—with one control plane for every pipeline.
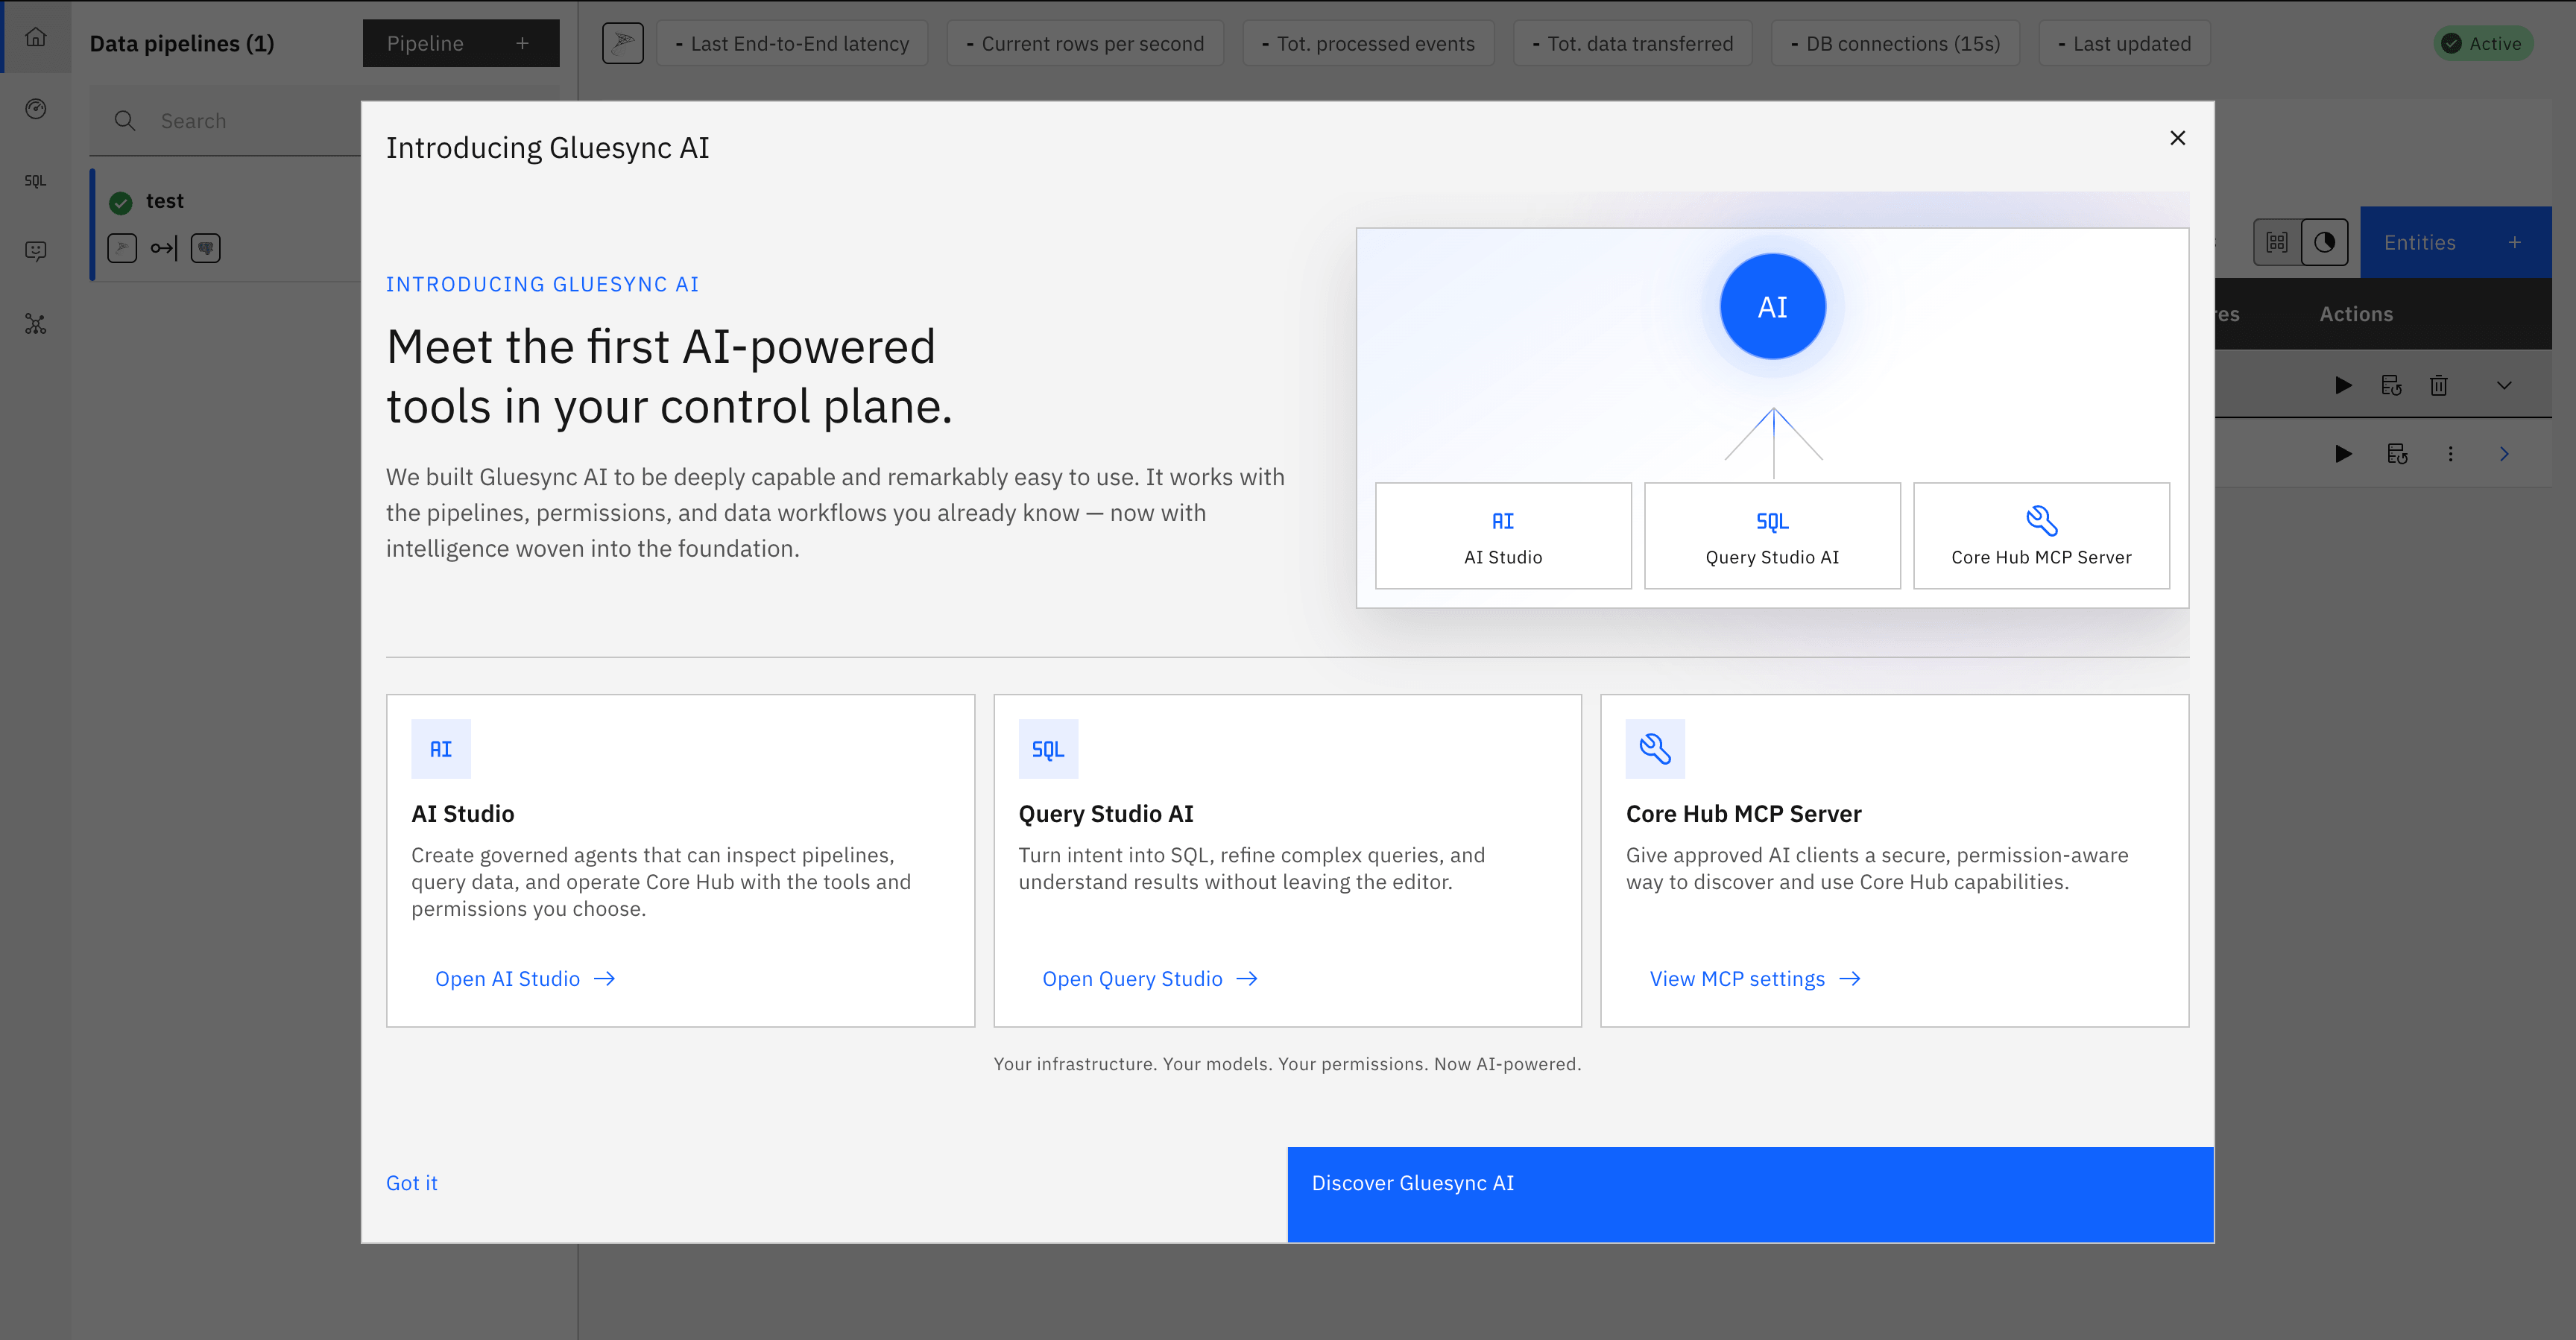
Gluesync 2.3.0: bring your own brain, pick your own write rules, and let the target fill in its own blanks
- AI Studio — build it, route it, run it, govern it
- Query Studio AI helper — it read the schema so you don’t have to
- PII discovery — labels everywhere, values only when you mean it
Start with the work
One platform, every stage of the data journey
Whether you are evaluating an architecture or running hundreds of pipelines, go straight to the guidance you need.
01 / Understand
See how Gluesync works
Learn how Core Hub, the Control Plane, and distributed Agents cooperate without forcing your data through a new central store.
02 / Deploy
Go from zero to running
Use the supported kit installer, or choose Docker Compose and Kubernetes when your infrastructure team needs more control.
03 / Integrate
Build your first pipeline
Configure source and target connectors, select your entities, and start continuous replication from the Control Plane.
04 / Operate
Know what your data is doing
Track delivery, health, and alerts from the product or connect the same operational signals to your observability stack.
Designed for hybrid reality
One control plane. Data stays in motion.
Gluesync coordinates real-time, event-based integration across relational databases, NoSQL systems, APIs, data lakes, and streaming platforms. Deploy Agents close to each system and manage the complete flow centrally.
-
Open by design. Use REST APIs and open-source Python and Node.js SDKs to extend and automate the platform.
-
Built for mixed estates. Connect homogeneous and heterogeneous systems without replacing the technology you already run.
-
Operable at scale. Configure, secure, observe, and troubleshoot pipelines from a shared control plane.
More than replication
Work with live data without stitching together another toolchain
Replicate
Move inserts, updates, and deletes continuously between the systems that run your business.
Query
Work across connected data through Query Studio and the federated tools provided by Core Hub.
Automate
Run pipeline and SQL actions on a schedule, respond to events, or integrate through APIs and the Core Hub MCP server.
Your first successful sync
A clear path from install to insight
The platform is modular. Getting started does not have to be.
- 01Deploy
Install Core Hub and open the Control Plane.
- 02Connect
Place Agents beside your source and target systems.
- 03Map
Choose entities and define how data should arrive.
- 04Sync
Run the snapshot, then keep every change moving.
- 05Observe
Follow throughput, freshness, health, and alerts.
Keep exploring
Everything you need to build with confidence
See where Gluesync is going
Follow the public roadmap for the capabilities moving from idea to delivery.
What is new in 2.3
Get the focused guide to the next Gluesync release train and its current availability.
Get expert support
Find troubleshooting guidance or open a case with the MOLO17 support team.
Choose an integration
Browse the growing catalog of supported databases, platforms, and protocols.
Ready when your data is